CLAP Sound Retrieval
Contrastive Language-Audio Pretraining for text-prompted sound retrieval and 2D embedding exploration
Project developed as part of the Deep Learning coursework at IMT Atlantique. Code and materials available on GitHub.
CLAP (Contrastive Language-Audio Pretraining) is a multimodal learning strategy that projects audio signals and natural language descriptions into a shared representation space. The model is trained via contrastive objectives to maximize mutual information between corresponding text-audio pairs while repelling non-matching pairs.
With an aligned representation space, the model unlocks:
- Zero-shot Sound Classification: Classifying audio clips into unseen categories using natural language prompts.
- Text-Prompted Audio Retrieval: Searching large sound archives using arbitrary descriptive sentences.
- Interactive Latent Exploration: Visualizing and analyzing clustering behavior of acoustic features.
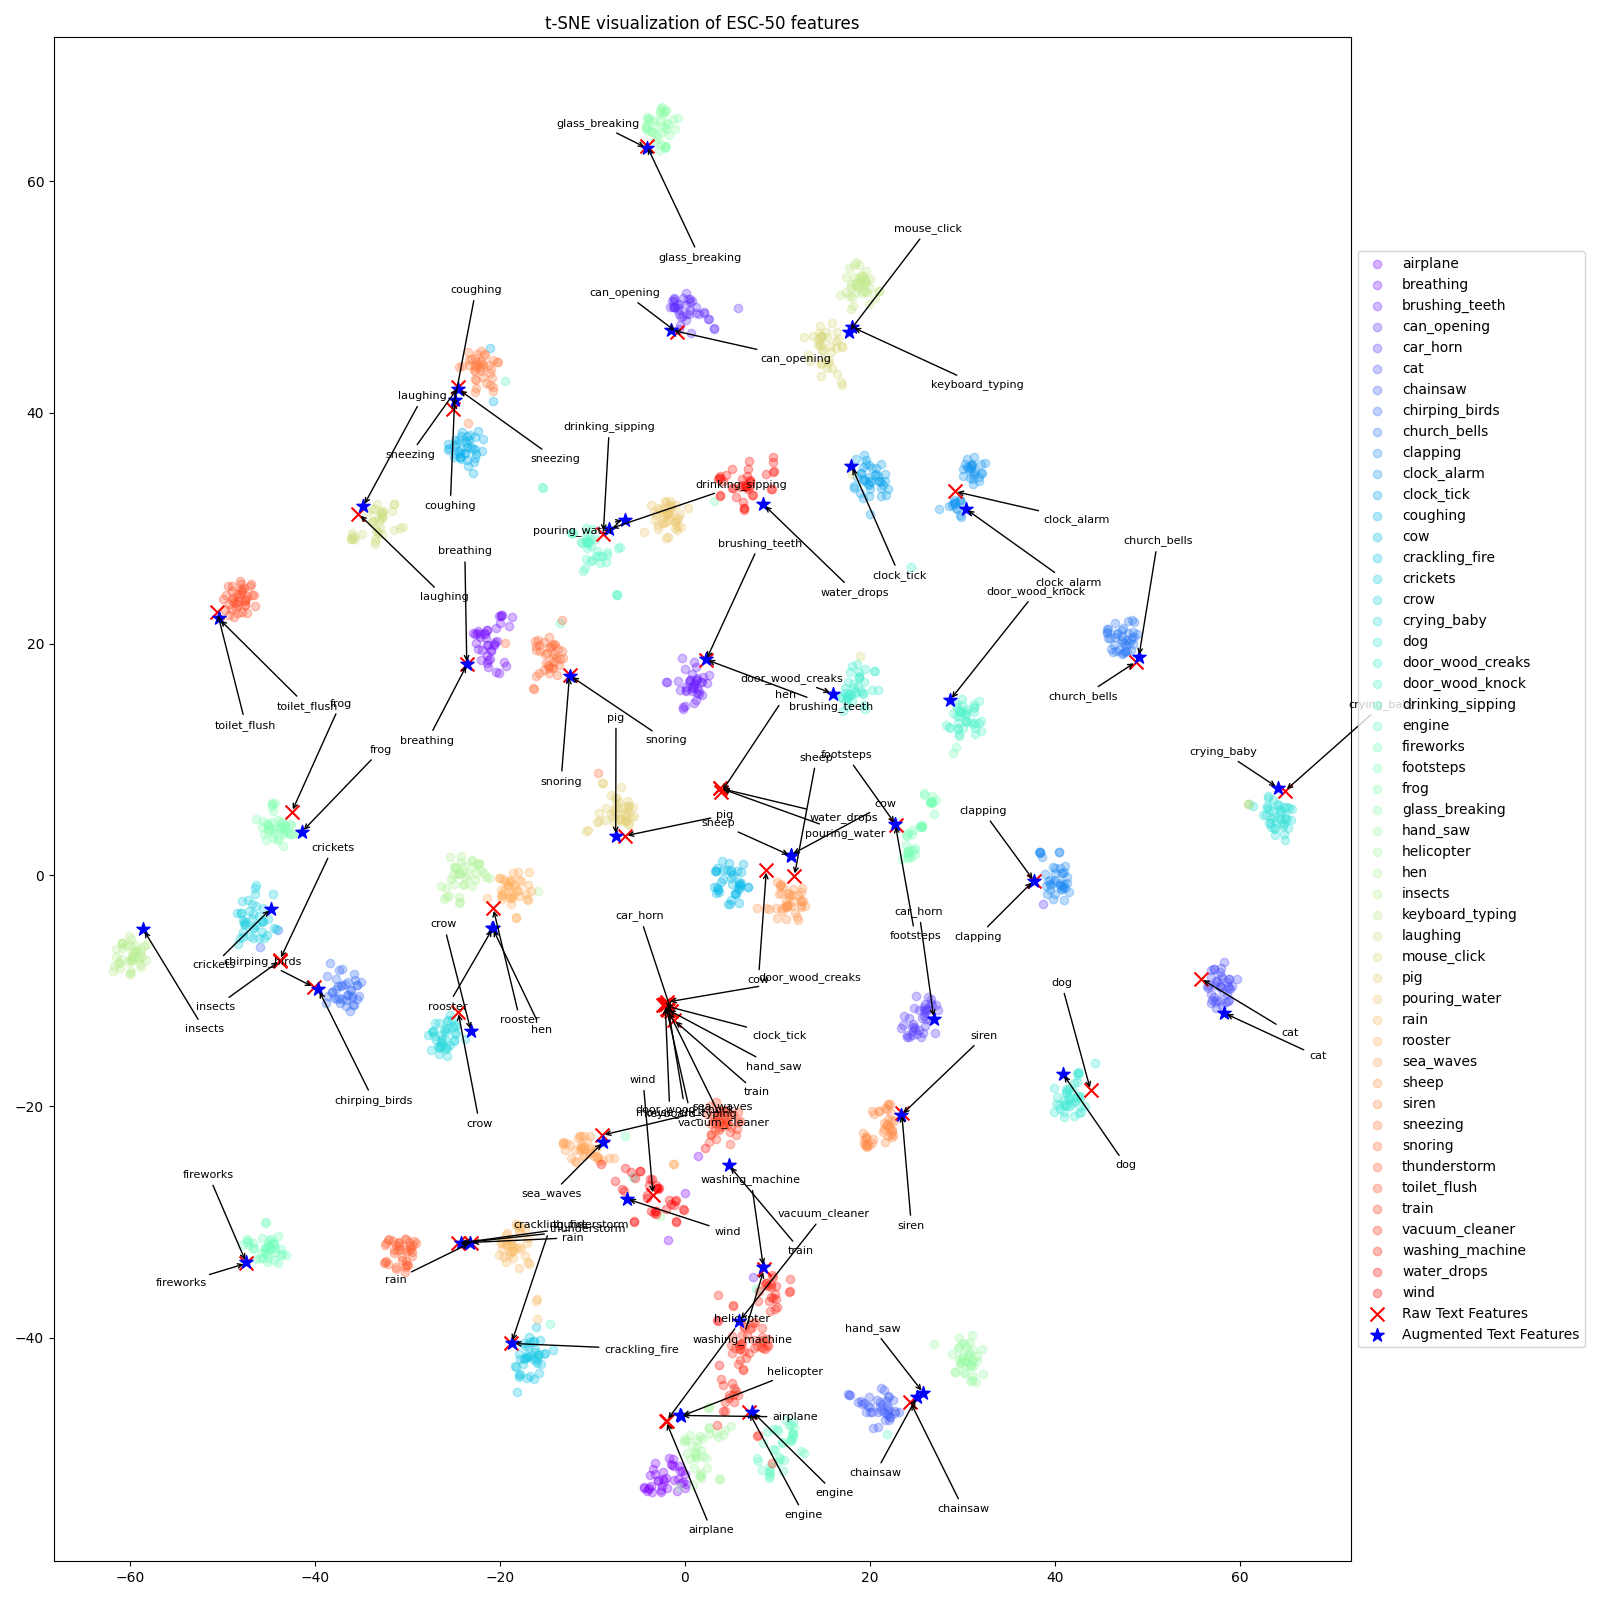
2D t-SNE projection of the aligned text-audio latent space evaluated on ESC-50.
Links
- Source Code: github.com/jonathanlys01/DL_2023_CLAP