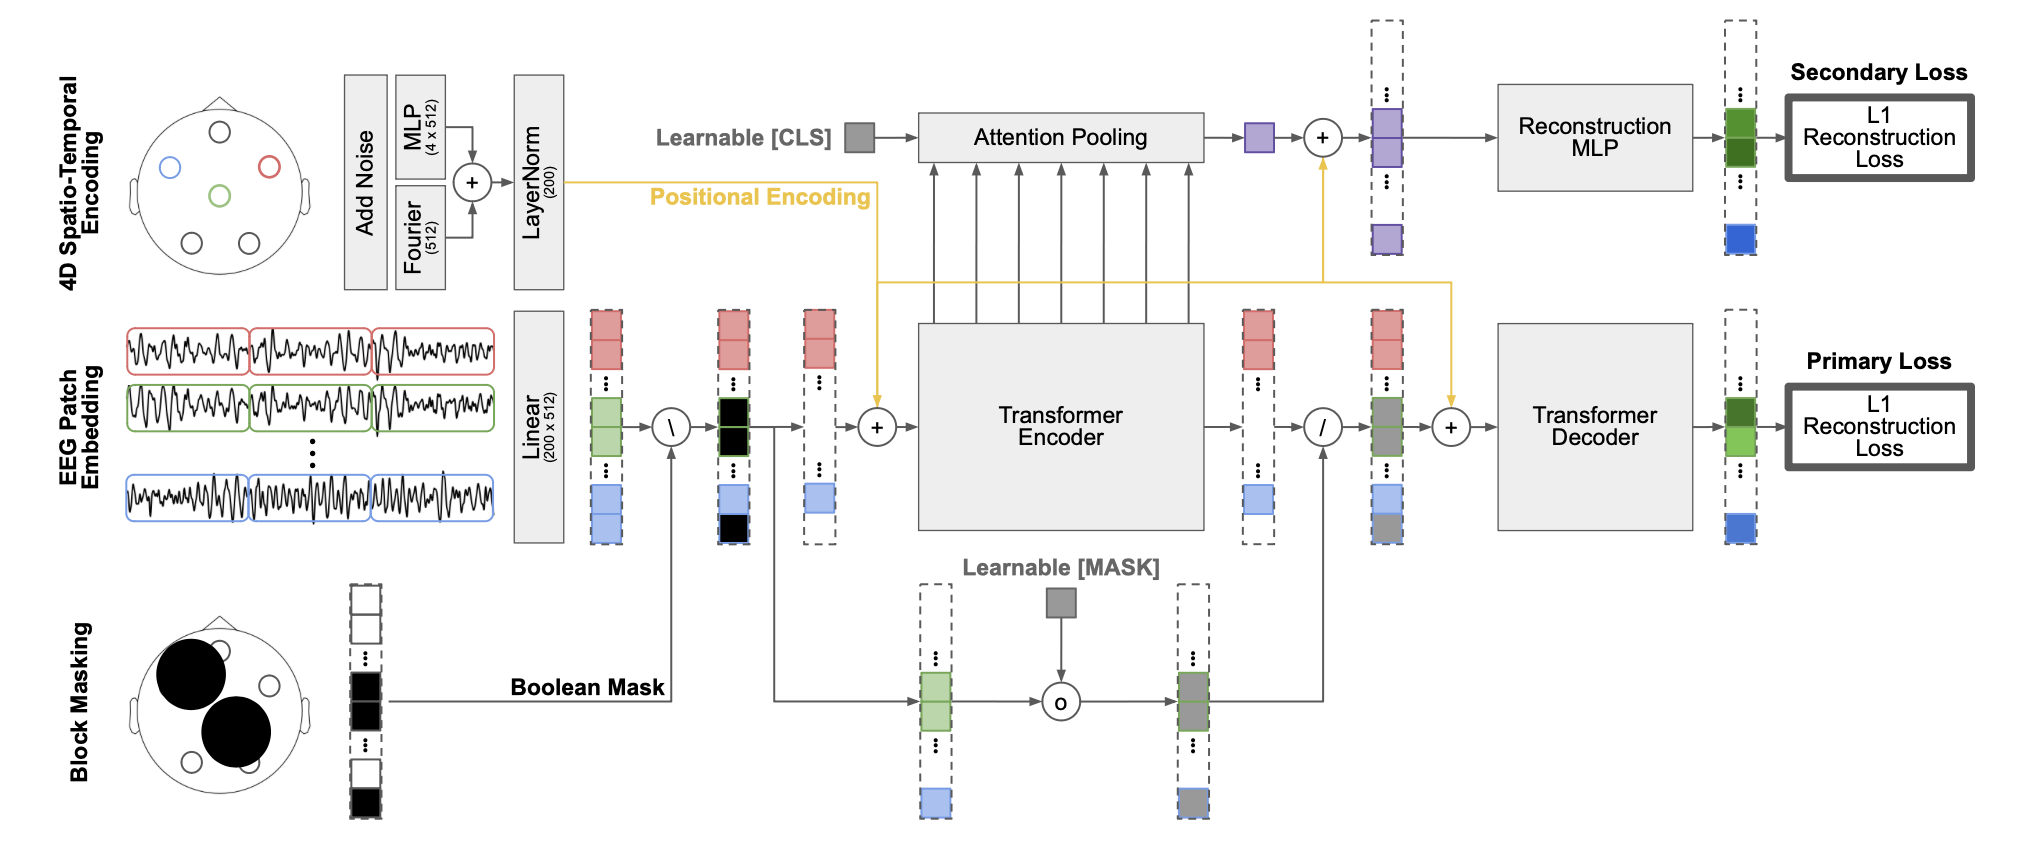
Foundation models have transformed AI by reducing reliance on task-specific data through large-scale pretraining. While successful in language and vision, their adoption in EEG has lagged due to the heterogeneity of public datasets, which are collected under varying protocols, devices, and electrode configurations. Existing EEG foundation models struggle to generalize across these variations, often restricting pretraining to a single setup, resulting in suboptimal performance, in particular under linear probing. We present REVE (Representation for EEG with Versatile Embeddings), a pretrained model explicitly designed to generalize across diverse EEG signals. REVE introduces a novel 4D positional encoding scheme that enables it to process signals of arbitrary length and electrode arrangement. Using a masked autoencoding objective, we pretrain REVE on over 60,000 hours of EEG data from 92 datasets spanning 25,000 subjects, representing the largest EEG pretraining effort to date. REVE achieves state-of-the-art results on 10 downstream EEG tasks, including motor imagery classification, seizure detection, sleep staging, cognitive load estimation, and emotion recognition. With little to no fine-tuning, it demonstrates strong generalization, and nuanced spatio-temporal modeling.
@inproceedings{elouahidi2025reve,title={REVE: A Foundation Model for EEG -- Adapting to Any Setup with Large-Scale Pretraining on 25,000 Subjects},author={El Ouahidi, Yassine and Lys, Jonathan and Thölke, Philipp and Farrugia, Nicolas and Pasdeloup, Bastien and Gripon, Vincent and Jerbi, Karim and Lioi, Giulia},booktitle={Advances in Neural Information Processing Systems (NeurIPS)},year={2025},doi={10.52202/085713-0760}}
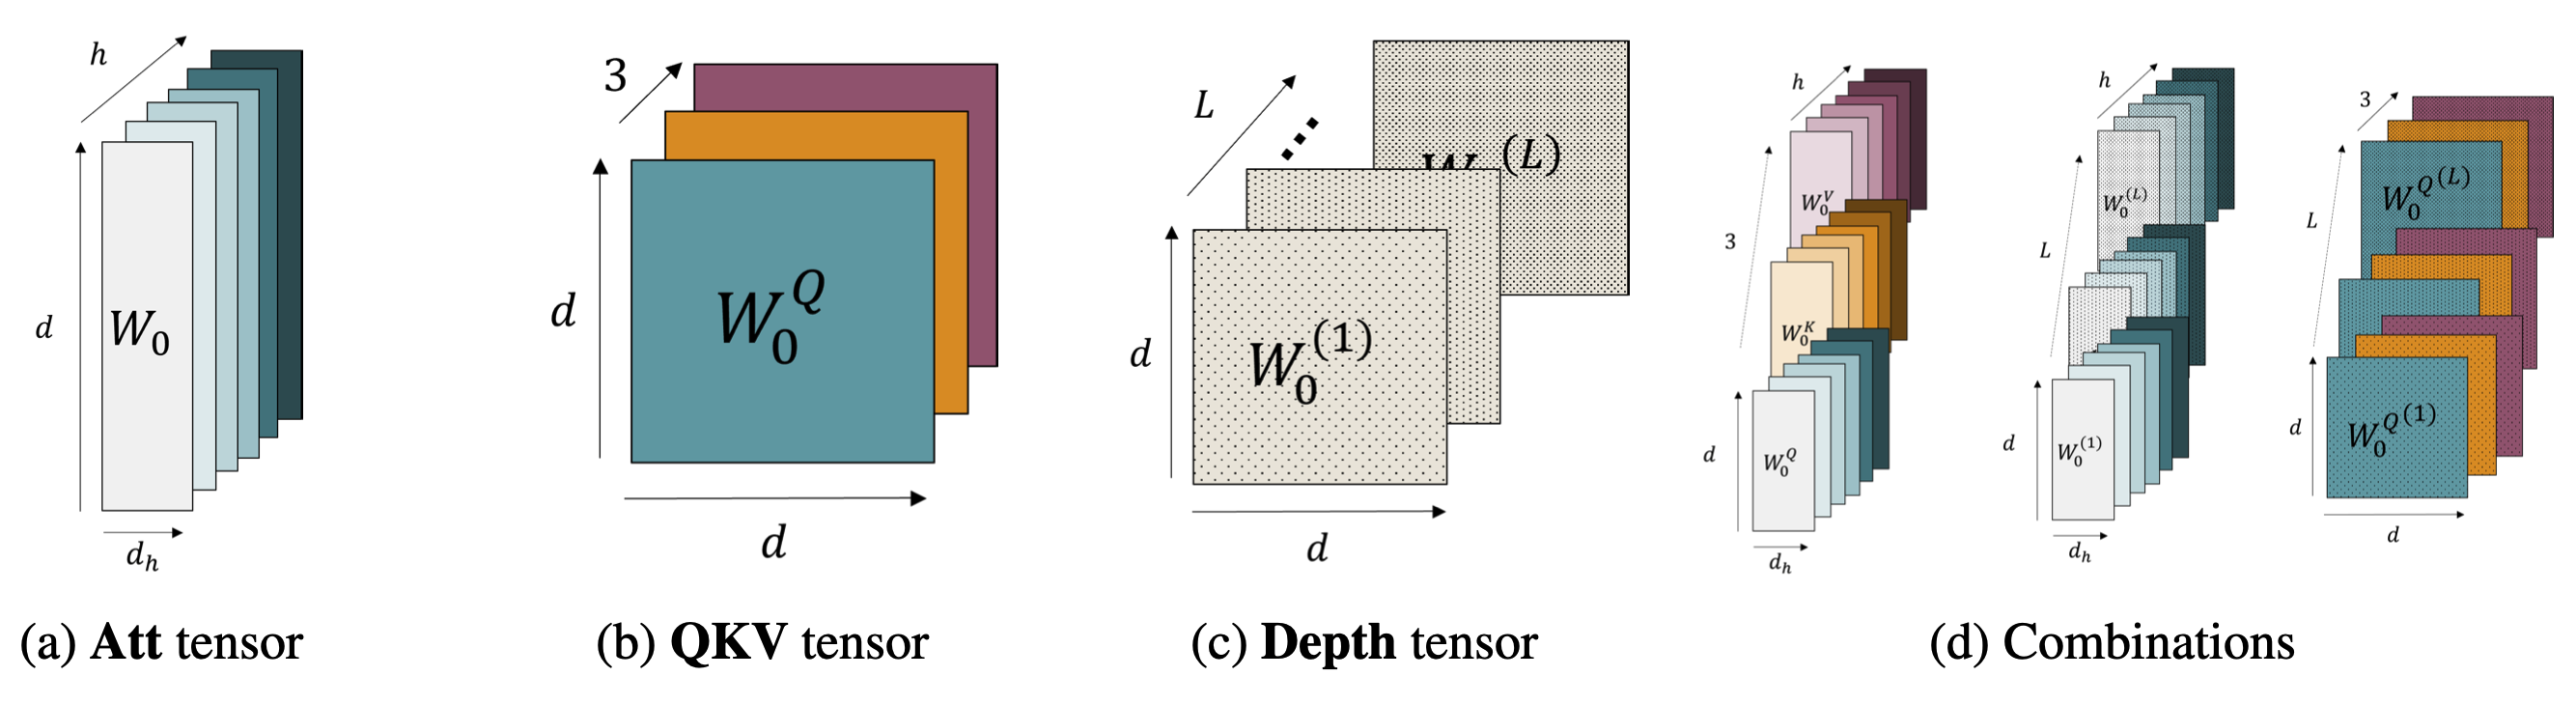
Low-Rank Adaptation (LoRA) is widely used to efficiently adapt Transformers by adding trainable low-rank matrices to attention projections. While effective, these matrices are considered independent for each attention projection (Query, Key, and Value) and each layer. Recent extensions have considered joint, tensor-based adaptations, but only in limited forms and without a systematic framework. We introduce TensLoRA, a unified framework that aggregates LoRA updates into higher-order tensors and models a broad family of tensor-based low-rank adaptations. Our formulation generalizes existing tensor-based methods and enables mode-specific compression rates, allowing parameter budgets to be tailored according to the modality and task. Experiments on vision and language benchmarks reveal that the tensor construction directly impacts performance, sometimes better than standard LoRA under similar parameter counts.
@inproceedings{marmoret2026tenslora,title={TensLoRA: Tensor Alternatives for Low-Rank Adaptation},author={Marmoret, Axel and Bensaid, Reda and Lys, Jonathan and Gripon, Vincent and Leduc-Primeau, François},booktitle={IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP)},year={2026},doi={10.1109/icassp55912.2026.11460572}}
Deep Learning architectures, and in particular Transformers, are conventionally viewed as a composition of layers. These layers are actually often obtained as the sum of two contributions: a residual path that copies the input and the output of a Transformer block. As a consequence, the inner representations (i.e. the input of these blocks) can be interpreted as iterative refinement of a propagated latent representation. Under this lens, many works suggest that the inner space is shared across layers, meaning that tokens can be decoded at early stages. Mechanistic interpretability even goes further by conjecturing that some layers act as refinement layers. Following this path, we propose inference-time inner looping, which prolongs refinement in pretrained off-the-shelf language models by repeatedly re-applying a selected block range. Across multiple benchmarks, inner looping yields modest but consistent accuracy improvements. Analyses of the resulting latent trajectories suggest more stable state evolution and continued semantic refinement. Overall, our results suggest that additional refinement can be obtained through simple test-time looping, extending computation in frozen pretrained models.
@inproceedings{lys2026innerloop,title={Inner Loop Inference for Pretrained Transformers: Unlocking Latent Capabilities Without Training},author={Lys, Jonathan and Gripon, Vincent and Pasdeloup, Bastien and Marmoret, Axel and Mauch, Lukas and Cardinaux, Fabien and Hacene, Ghouthi Boukli},booktitle={European Signal Processing Conference (EUSIPCO)},year={2026},}
Large Language Models (LLMs) are trained with next-token prediction, implemented in autoregressive Transformers via causal masking for parallelism. This creates a subtle misalignment: residual connections tie activations to the current token, while supervision targets the next token, potentially propagating mismatched information if the current token is not the most informative for prediction. In this work, we empirically localize this input-output alignment shift in pretrained LLMs, using decoding trajectories over tied embedding spaces and similarity-based metrics. Our experiments reveal that the hidden token representations switch from input alignment to output alignment deep within the network. Motivated by this observation, we propose a lightweight residual-path mitigation based on residual attenuation, implemented either as a fixed-layer intervention or as a learnable gating mechanism. Experiments on multiple benchmarks show that these strategies alleviate the representation misalignment and yield improvements, providing an efficient and general architectural enhancement for autoregressive Transformers.
@inproceedings{lys2026residual,title={Residual Connections and the Causal Shift: Uncovering a Structural Misalignment in Transformers},author={Lys, Jonathan and Gripon, Vincent and Pasdeloup, Bastien and Marmoret, Axel and Mauch, Lukas and Cardinaux, Fabien and Hacene, Ghouthi Boukli},booktitle={European Signal Processing Conference (EUSIPCO)},year={2026},}
Discrete diffusion models are promising alternatives to autoregressive approaches for text generation, yet their decoding methods remain under-studied. Standard autoregressive search procedures, such as beam search, do not directly apply to iterative denoising, where hypotheses are complete intermediate sequences rather than left-to-right prefixes. Furthermore, existing diffusion decoding procedures only provide limited control over the diversity and coverage of retained hypotheses. In this work, we introduce D5P4, a beam-style decoding method tailored to discrete diffusion models, which casts intermediate beam selection as MAP inference under a partitioned Determinantal Point Process. This yields a model-internal batch objective that balances quality and diversity without external verifiers. Experiments on open-ended generation, question answering, and mathematical reasoning show that D5P4 improves diversity and pass@k coverage while matching or surpassing baseline quality and fidelity.
@article{lys2026d5p4,title={D5P4: Partition Determinantal Point Process for Diversity in Parallel Discrete Diffusion Decoding},author={Lys, Jonathan and Gripon, Vincent and Pasdeloup, Bastien and Marmoret, Axel and Mauch, Lukas and Cardinaux, Fabien and Hacene, Ghouthi Boukli},journal={arXiv preprint arXiv:2603.19146},year={2026},}